Top all-time · #5033

Aleksey Charapko
Personal blog · charap.cosystemsscience
Aleksey Charapko's personal blog at charap.co covers systems and science. Since 2016, 15 different Hacker News readers have linked it 24 times, most often “Metastable Failures in Distributed Systems”. It is still writing: the last post was on 2026-05-02, and you can follow it by feed.
Most-linked posts?
- Metastable Failures in Distributed Systems3 people · 5 mentions · first linked 2021-05-24
- Metastable Failures and Interactions Between Systems2 people · 2 mentions · first linked 2025-12-26
What Hacker News says?
> I don't care about consistency. Fair nuff, I asked because I was curious if you were assuming that eventual consistency was necessary for high availability. > Write rate isn't really much of a consideration since it's almost embarrassingly low (hundreds per second). Yup, looks like my concern above is the case. A single consensus replica set will do that no problem. I'd use raft if you're in a single geo location…
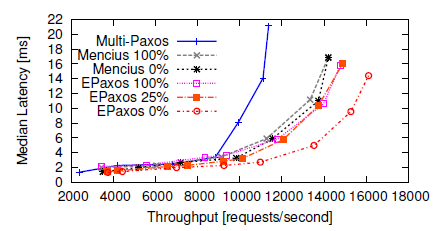
Comment linking /wp-content/uploads/2015/10/latency_over_throughput.png
on “Writing a very fast cache service with millions of entries in Go”Submitted Paxos vs. Raft: Have we reached consensus on distributed consensus? as a story · 183 points
HN discussionI think this paper is super important, and anybody who designs or runs big systems should read it and take the core point to heart. As system designers, we're very used to thinking about systems as 'stable' and 'unstable', where stability is good, and instability is bad. What this paper points out is that many kinds of distributed systems have multiple 'stable' modes, some of which are modes where the system is stab…
Comment linking /metastable-failures-in-distributed-systems/
on “Metastable Failures in Distributed Systems [pdf]”Submitted Scalable but Wasteful, or why fast replication protocols are slow as a story · 93 points
HN discussion> This isn’t a showstopper event, it’s a process stopper event. Again, the PAR paper describes the specific examples where a single disk sector failure on a single replica can be a showstopper event — for the whole cluster, even precluding reconfiguration since the log might no longer be functional. I know I've been hammering this point (single local disk sector failure = global cluster data loss or else global clus…
Comment linking /reading-group-viewstamped-replication-revisited/
on “Paxos automatically determined safe and secure”Submitted Metastable Failures in Distributed Systems as a story · 50 points
HN discussion“Paxos is one of the first and most celebrated ideas that laid the foundation for how different things come to an agreement asynchronously” “Most—if not all—consensus algorithms fundamentally derive concepts from Paxos” It's not well known (even in the field of distributed systems) that in fact Viewstamped Replication pioneered the field of consensus in 1988, a year before Paxos, with an intuitive algorithm essentia…
Comment linking /reading-group-viewstamped-replication-revisited/
on “Paxos automatically determined safe and secure”Submitted Viewstamped Replication Revisited as a story · 20 points
HN discussionAleksey Charapko's DistSys Reading Group had an interesting discussion on RAFT, Paxos and Viewstamped Replication recently, where I was able to present James Cowling's 2012 revision of VSR: http://charap.co/reading-group-viewstamped-replication-revis... RAFT is more within the tradition and family of Viewstamped Replication than Multi-Paxos, and VSR has some optimizations beyond RAFT that are interesting, especially…
Comment linking /reading-group-viewstamped-replication-revisited/
on “Raft Consensus Protocol”Submitted Metastable Failures and Interactions Between Systems as a story · 3 points
HN discussionWhile reading Aleksey’s blog[0] linked from yours it struck me that this sounds a great deal like (real world) traffic engineering. A backup occurs, the traffic grinds to a halt, and after the blockage is removed it takes a very long time for the system to recover. If traffic is heavy enough, even just a small slowdown is enough to cause prolonged pain. [0]: http://charap.co/metastable-failures-in-distributed-system…
Comment linking /metastable-failures-in-distributed-systems/
on “Metastable Failures in Distributed Systems”Submitted The Cost of Garbage Collection for State Machine Replication as a story · 3 points
HN discussionThere’s also the part where the disaster recovery site apparently fell over under the load (which, OK, is a thing that might happen) and they needed to code up limits on the fly (and that is not OK; I don’t have the slightest idea how one might test this, but if you’re building a “disaster” site it seems like you’d need to figure it out): > When services were turned up there, we experienced a thundering herd problem…
Comment linking /metastable-failures-in-distributed-systems/
on “Post Mortem on Cloudflare Control Plane and Analytics Outage”Submitted Metastability in Recovery: Cascading Recovery with a Loop as a story · 2 points
HN discussionSubmitted Metastable Failures and Interactions Between Systems as a story · 2 points
HN discussionSubmitted Academic Chat with Murat and Aleksey: 5 CS of the Invisible Curriculum as a story · 2 points
HN discussionSubmitted OLTP Through the Looking Glass 16 Years Later: Communication Is the Bottleneck as a story · 2 points
HN discussionSubmitted Method Overloading the Circuit as a story · 2 points
HN discussionSubmitted Viewstamped Replication Revisited as a story · 2 points
HN discussionSubmitted Metastable Failures in Distributed Systems as a story · 2 points
HN discussionSubmitted How AI Is Upending Systems Research as a story · 1 points
HN discussionSubmitted Review: Implementing Linearizability at Large Scale and Low Latency as a story · 1 points
HN discussionSubmitted Cloudy Forecast: How Predictable Is Communication Latency in the Cloud? as a story · 1 points
HN discussionSubmitted Distibuted Systems reading group spring term reading list as a story · 1 points
HN discussion