Top all-time · #516
Lil'Log
Personal blog · lilianweng.github.ioaimathprogramming
Lil'Log is a personal blog at lilianweng.github.io about ai, math and programming. Since 2018, 114 different Hacker News readers have linked it 149 times, most often “Prompt Engineering: Steer a large pretrained language model to do what you want”. It is still writing: the last post was on 2026-07-04, and you can follow it by feed.
Often recommended · 16 of 40 sampled comments recommend it?
Why HN links it
HN readers link Lil'Log as an intuitive entry point to ML topics such as diffusion, attention, transformers and RL, and for the maths behind popular models.
- Recommended for · 16 comments
- Called a good starting point, a great read, a goldmine, and one of the best prompt-engineering howtos.
Summarised by Claude from a sample of 40 HN comments that link here. Each comment is marked recommending, critical or neutral (citing without judging); how this works.
Document my learning notes.
Most-linked posts?
- Prompt Engineering: Steer a large pretrained language model to do what you want8 people · 8 mentions · first linked 2023-03-20
- Extrinsic Hallucinations in LLMs7 people · 7 mentions · first linked 2024-07-08
- What Are Diffusion Models?7 people · 7 mentions · first linked 2022-04-06
- Why We Think6 people · 7 mentions · first linked 2025-05-17
- The Transformer Family Version 2.06 people · 6 mentions · first linked 2023-01-28
- Attention Mechanism Explained5 people · 7 mentions · first linked 2023-02-11
- Harness Engineering for Self-Improvement5 people · 5 mentions · first linked 2026-07-07
- Domain Randomization for Sim2Real Transfer4 people · 5 mentions · first linked 2019-05-11
- LLM Powered Autonomous Agents4 people · 4 mentions · first linked 2023-06-27
- A Long Peek into Reinforcement Learning4 people · 4 mentions · first linked 2018-09-06
What Hacker News says?
I recommend this blog post: https://lilianweng.github.io/posts/2021-07-11-diffusion-mode... Personally, I find the core diffusion papers pretty dense and difficult to follow, so the blog post is where I'd begin. https://arxiv.org/pdf/1503.03585.pdf This paper is a decent starting point on the literature side, but it's a doozy. Both the paper and blog post are pretty math heavy. I have not yet found a really clear in…
Comment linking /posts/2021-07-11-diffusion-models/
on “Dall-E 2”Submitted Are deep neural networks dramatically overfitted? (2019) as a story · 209 points
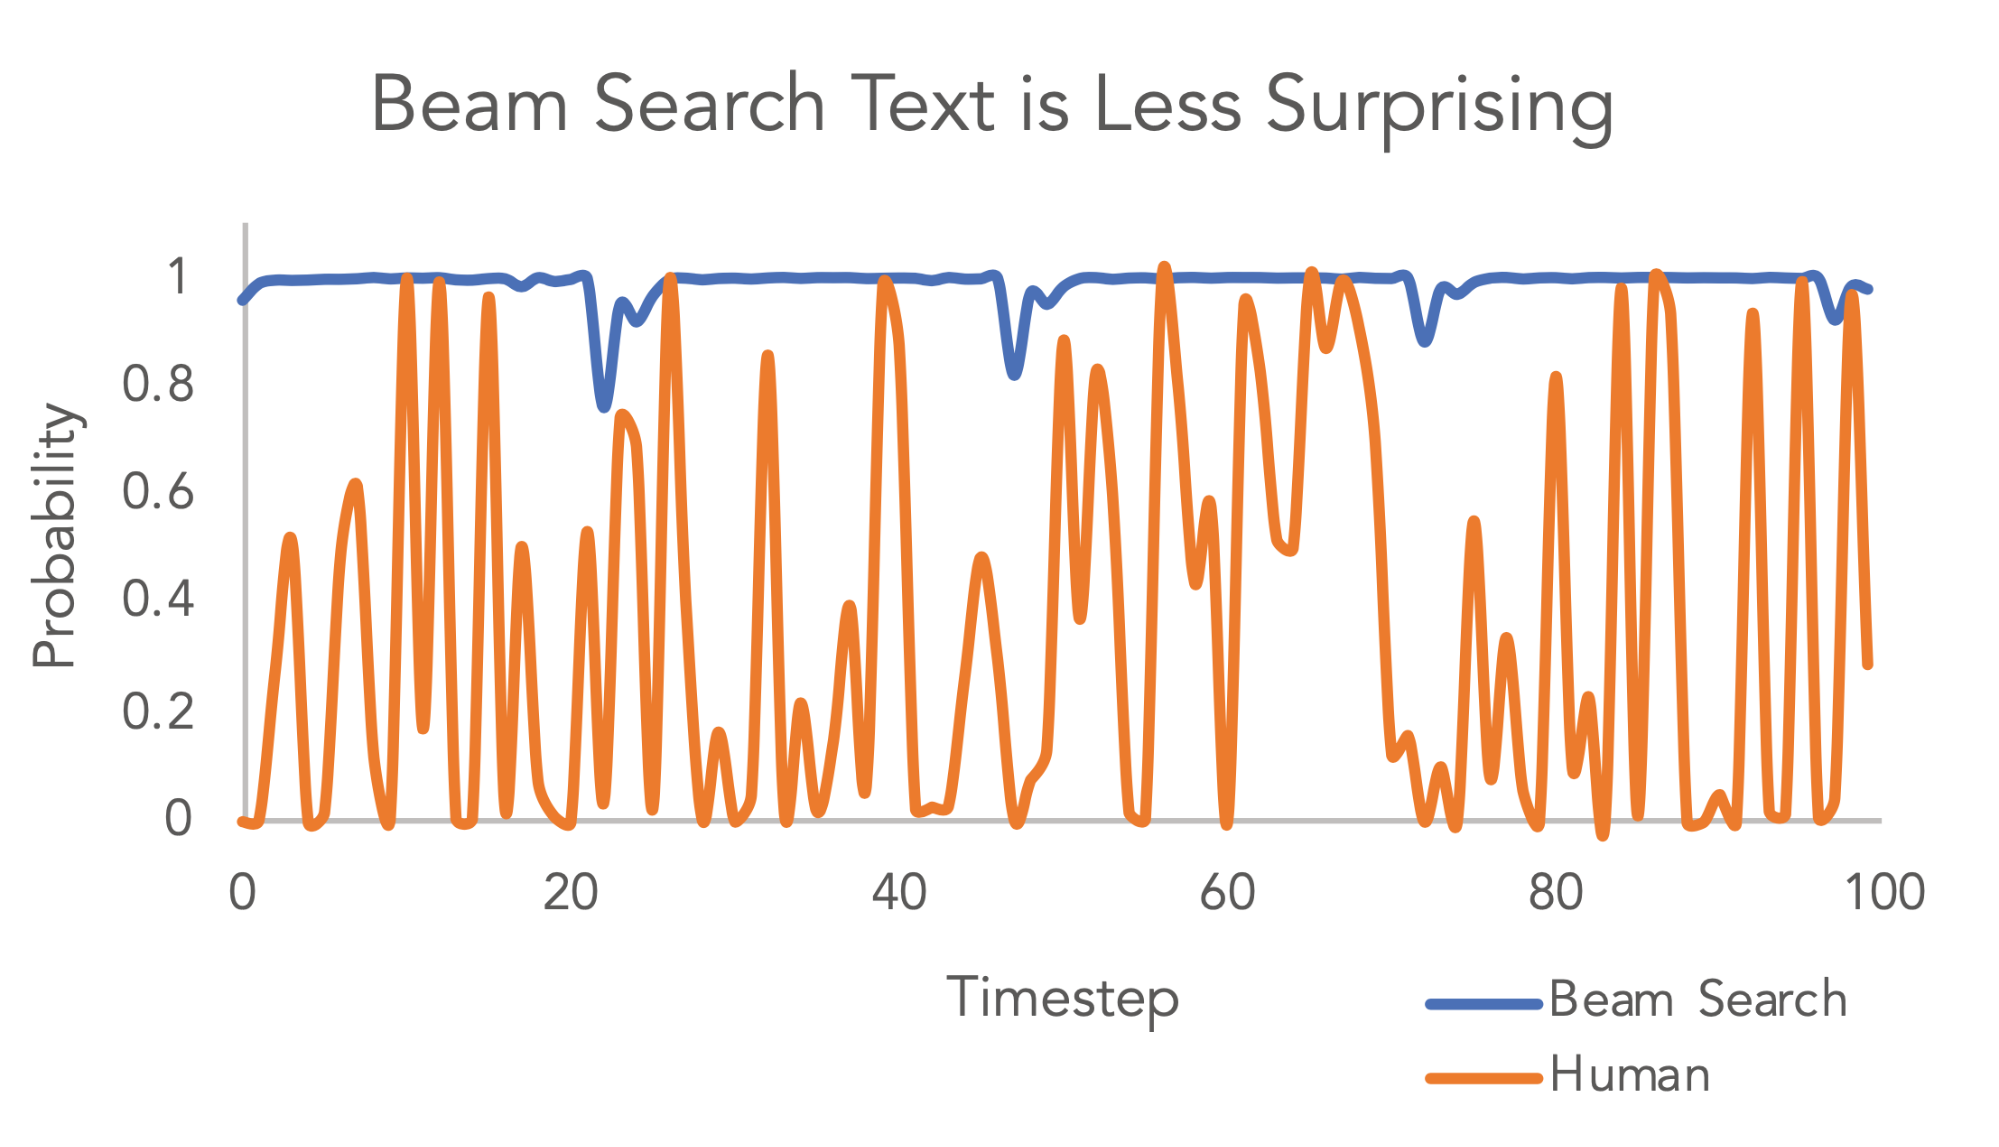
HN discussionIn practice, beam search doesn't seem to work well for generative models. Temperature and top_k (two very similar parameters) were both introduced to account for the fact that human text is unpredictable stochastically for each sentence someone might say as such - as shown in this 2021 similar graph/reproduction of an older graph from the 2018/2019 HF documentation: https://lilianweng.github.io/posts/2021-01-02-cont…
Comment linking /posts/2021-01-02-controllable-text-generation/beam_search_less_surprising.png
on “But what is a GPT? Visual intro to Transformers [video]”Submitted A (Long) Peek into Reinforcement Learning as a story · 160 points
HN discussionThis is a classic... This isn't the first time this piece has been posted before either. Here's one from FT last year[0] or Bloomberg[1]. You can find more. Google certainly played a major role, but it is too far to say they invented it or that they are the ones that created modern AI. Like Einstein said, shoulder of giants. And realistically, those giants are just a bunch of people in trench coats. Millions of rese…
Comment linking /posts/2018-06-24-attention/
on “The Google employees who created transformers”Submitted Why We Think as a story · 147 points
HN discussionSounds like you need an agent system, some libs are mentioned here: https://lilianweng.github.io/posts/2023-06-23-agent/
Comment linking /posts/2023-06-23-agent/
on “What we've learned from a year of building with LLMs”Submitted A Long Peek into Reinforcement Learning as a story · 147 points
HN discussionGood article, but I feel that it misses an important property of diffusion models that they model the score function (derivative of log prob) [1] and that diffusion sampling is akin to Langevin dynamics [2]. IMO these explain why it's easier to train these models than GANs, because of an easier modeling objective. [1] https://yang-song.net/blog/2021/score/ [2] https://lilianweng.github.io/posts/2021-07-11-diffusion-…
Comment linking /posts/2021-07-11-diffusion-models/
on “Diffusion models from scratch, from a new theoretical perspective”Submitted Learning with Not Enough Data: Semi-Supervised Learning as a story · 145 points
HN discussionFor an technical intro for word2vec (what's that exactly, how to train it): https://lilianweng.github.io/lil-log/2017/10/15/learning-wor... and its readable implementation in PyTorch: https://adoni.github.io/2017/11/08/word2vec-pytorch/ . And just for getting idea why does it work, and play with examples in your browser: http://p.migdal.pl/2017/01/06/king-man-woman-queen-why.html
Comment linking /lil-log/2017/10/15/learning-word-embedding.html
on “Understanding word vectors”Submitted A Long Peek into Reinforcement Learning as a story · 133 points
HN discussionAKA 'sim2real' gap for googling purposes. related: https://lilianweng.github.io/lil-log/2019/05/05/domain-rando...
Comment linking /lil-log/2019/05/05/domain-randomization.html
on “AirSim: open-source simulator for autonomous vehicles”Submitted What Are Diffusion Models? as a story · 118 points
HN discussionYes, this is an area of active research. For example https://lilianweng.github.io/posts/2023-10-25-adv-attack-llm...
Comment linking /posts/2023-10-25-adv-attack-llm/
on “Adversarial policies beat superhuman Go AIs (2023)”Submitted How to train large models on many GPUs? as a story · 108 points
HN discussionCheck out Lilian Weng's blog https://lilianweng.github.io/posts/2023-01-27-the-transforme...
Comment linking /posts/2023-01-27-the-transformer-family-v2/
on “Better and Faster Large Language Models via Multi-Token Prediction”Submitted Thinking about high-quality human data as a story · 103 points
HN discussionA fully illustrated article [1] And Lilian Weng blog on self-supervision [2] .. CPC is .. translating a generative modeling problem to a classification problem... uses cross-entropy loss to measure how well the model can classify the “future” representation amongst a set of unrelated “negative” samples... [1] https://ankeshanand.com/blog/2020/01/26/contrative-self-supe... [2] https://lilianweng.github.io/lil-log/201…
Comment linking /lil-log/2019/11/10/self-supervised-learning.html
on “Visual Introduction to Self Supervised Learning”Submitted Contrastive Representation Learning as a story · 93 points
HN discussionI am curious what additional attacks knowing the last layer of an LLM enables. Eg you go from a black box attack to some sort of white box [1] Does it help with adversarial prompt injection? What % of the network do you need to know to identify whether an item was included in the pretraining data with k% confidence? I assume we will see more of these and possibly complex zero days. Interesting if you can steal any n…
Comment linking /posts/2023-10-25-adv-attack-llm/
on “Stealing Part of a Production Language Model”Submitted The Multi-Armed Bandit Problem and Its Solutions (2018) as a story · 92 points
HN discussionThe differences are pretty subtle... If you want an overview of the whole zoo, see https://lilianweng.github.io/lil-log/2020/04/07/the-transfor... https://www.pragmatic.ml/a-survey-of-methods-for-incorporati... https://arxiv.org/abs/2009.06732#google https://www.gwern.net/GPT-2#efficient-attention
Comment linking /lil-log/2020/04/07/the-transformer-family.html
on “Rethinking Attention with Performers”Submitted Contrastive Representation Learning as a story · 87 points
HN discussionI'm fairly certain that the model was not at all trained on language data. It's just that the "neural architecture" (specifically, the Transformer architecture) was first discovered in the NLP realm. If your question is why does an architecture designed for NLP work well for aminoacid sequences, it turns out that the Transformer architecture is surprisingly versatile. It works amazingly well for other sequence-like…
Comment linking /posts/2018-06-24-attention/
on “AlphaFold’s new rival? Meta AI predicts shape of 600M proteins”Submitted Flow-Based Deep Generative Models as a story · 75 points
HN discussionSee contrastive losses and siamese networks, like here (where they use L2 distance): https://lilianweng.github.io/posts/2021-05-31-contrastive/ If documents are similar, you want the two embeddings to be close to each other, if they are dissimilar, you want them to be far apart. Binary relevance judgements of course don't necessarily produce an ordering, but usually over a large enough set of training examples some…
Comment linking /posts/2021-05-31-contrastive/
on “SentenceTransformers: Python framework for sentence, text and image embeddings”Submitted From GAN to WGAN (2017) as a story · 67 points
HN discussionWhile Transformer's Self Attention(SA) is great, there are many applications where SA doesn't apply. For a more comprehensive overview of attention mechanisms, I often find myself coming back to Lilian Weng's post: https://lilianweng.github.io/lil-log/2018/06/24/attention-at...
Comment linking /lil-log/2018/06/24/attention-attention.html
on “Attention Mechanism in Deep Learning”Submitted Generalized Language Models as a story · 40 points
HN discussion