Top all-time · #2890

Bits'n'Bites
Personal blog · bitsnbites.euprogrammingsystemshardware
Bits'n'Bites is a personal blog at bitsnbites.eu about programming, systems and hardware. Since 2011, 25 different Hacker News readers have linked it 32 times, most often “Debunking CISC vs. RISC code density (2022)”. It is still writing: the last post was on 2026-02-04, and you can follow it by feed.
Too few sampled comments (14) to say how often HN recommends it.?
Why HN links it
HN readers link Bits'n'Bites for benchmarks of OS process and file primitives (fork, exec, Windows file creation), comparisons of CPU instruction sets and code density, and the MRISC32 CPU design.
Summarised by Claude from a sample of 14 HN comments that link here. Each comment is marked recommending, critical or neutral (citing without judging); how this works.
Most-linked posts?
- Debunking CISC vs. RISC code density (2022)5 people · 6 mentions · first linked 2022-12-02
- Benchmarking OS primitives5 people · 5 mentions · first linked 2018-03-18
- /benchmarking-os-primitives/2 people · 2 mentions · first linked 2022-03-01
- Fundamental flaws of SIMD ISAs (2021)2 people · 2 mentions · first linked 2024-10-25
What Hacker News says?
>Stuff is just [...] faster on windows Windows is the slowest of OSes, see http://www.bitsnbites.eu/benchmarking-os-primitives/
Comment linking /benchmarking-os-primitives/
on “Apple Plans to Use Its Own Chips in Macs from 2020, Replacing Intel”Submitted Fundamental flaws of SIMD ISAs (2021) as a story · 153 points
HN discussionIt's really important in TDD to know that your test fails when the code you write for that feature it is missing. If it doesn't fail, that's a false positive. The prescribed pattern is, you write your test (it should be red), you write your code (it should turn green), you commit, push to CI, look at the rest of the tests, make sure none of them turned red... take another look at the code, refactor, commit, push to…
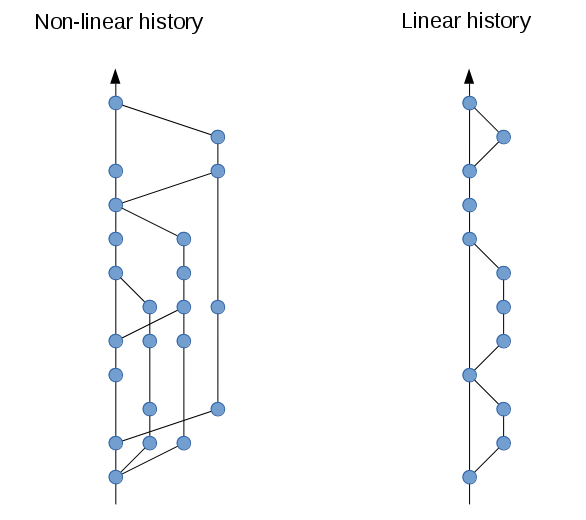
Comment linking /wp-content/uploads/2015/12/1-nonlinear-vs-linear.png
on “TDD did not live up to expectations”Submitted The MRISC32 – A vector first CPU design as a story · 87 points
HN discussionVery true (hence "most" not "all" in my statement :) ), but with AV disabled it's more or less on par with MacOS: https://www.bitsnbites.eu/benchmarking-os-primitives/ (not the best comparison given the wide variety of hardware in play, but for orders of magnitude it's probably good enough) File creation on Windows is similarly massively impacted by search & AV.
Comment linking /benchmarking-os-primitives/
on “Fork() is evil; vfork() is goodness; afork() would be better; clone() is stupid”Submitted Benchmarking OS primitives as a story · 72 points
HN discussionI have a Dell XPS (2018?), 16GB RAM, 512GB SSD, i7 and 3 year on-site warranty. I am running Linux Mint on it for Android development (Windows is much slower for building Android apps, because NTFS is slow at handling lots of small files - http://www.bitsnbites.eu/benchmarking-os-primitives/ ). I am really satisfied with the notebook and I had a Macbook for about a year before buying the XPS. There basically maybe 2…
Comment linking /benchmarking-os-primitives/
on “Appl Still Hasn’t Fixd Its MacBook Kyboad Problm”Submitted Three Fundamental Flaws of SIMD as a story · 56 points
HN discussionGreat observation. And in fact "serverless" is the way that Unix network servers used to work: https://en.wikipedia.org/wiki/Inetd CGI is also the way the web used to work. Spawning processes has only gotten faster since then. The entire "process spawning doesn't scale to the modern web" argument is completely and totally bogus. Today, spawning a process in Linux is only 10-20 microseconds slower than creating a thr…
Comment linking /benchmarking-os-primitives/
on “OpenBSD, C, httpd and SQLite – Web App stack”Submitted Compression of JavaScript programs as a story · 23 points
HN discussion> The first Google result I found agrees: https://www.bitsnbites.eu/cisc-vs-risc-code-density/ This isn't a great metric for 2 reasons. Firstly, it's looking at static rather than dynamic instruction counts, and 2nd x86 tends to get bigger vectorized implimentations, but these are often on bigger vectors so the "instructions per data" which is the more important metric in many cases is lower. https://news.ycombinato…
Comment linking /cisc-vs-risc-code-density/
on “An Interview with Zen Chief Architect Mike Clark”Submitted A tidy, linear Git history as a story · 22 points
HN discussion> it also gives us better density overall by having smaller instructions. x86 can put more work into each instruction byte, so we can have denser binaries and increase performance that way. Is that really true? I was under the impression that ARM core density was better than x86. The first Google result I found agrees: https://www.bitsnbites.eu/cisc-vs-risc-code-density/ > It may take a little bit more microarchitec…
Comment linking /cisc-vs-risc-code-density/
on “An Interview with Zen Chief Architect Mike Clark”Submitted Muon Baryon, an HTML5/WebGL demo in 6k JavaScript as a story · 12 points
HN discussionNo one's perfect with this stuff. If you don't believe me, clone git itself ($ git clone https://github.com/git/git ) and open up the repo in tig(1) https://github.com/jonas/tig To be honest, I only in the past 2 years even bothered to view ($ git log --graph). Regardless of --graph getting wide now and then, I always visualize my git history as a straight line. Also, sometimes having a non-linear history is inevita…
Comment linking /a-tidy-linear-git-history/
on “Git: Using Advanced Rebase Features for a Clean Repository”Submitted Doing a sound synth in JavaScript as a story · 6 points
HN discussion> The average A64 instruction does slightly less work than the average AMD64 instruction so the net result is that it makes sense to have slightly wider decoders I'm not sure that the difference is that big. A64 actually has quite powerful instructions, and some of them do more work than similar x86 instructions (madd and ubfx come to mind). In my testing A64 code often has fewer instructions than x86: https://www.b…
Comment linking /cisc-vs-risc-code-density/
on “Quake on an FPGA (MRISC32 CPU) [video]”Submitted Debunking CISC vs. RISC code density (2022) as a story · 3 points
HN discussionWow, how crazy is this? This guy: * Designed a 32-bit ISA with vector instructions [0] * Implemented it on an FPGA * Wrote a gcc backend for his ISA [1] * Ported Quake, and it seems to run pretty well (Quake required a high-end Pentium back in the day) Now this is a full-stack developer. [0] https://www.bitsnbites.eu/the-mrisc32-a-vector-first-cpu-des... [1] https://gitlab.com/mrisc32/mrisc32-gnu-toolchain
Comment linking /the-mrisc32-a-vector-first-cpu-design/
on “Quake on an FPGA (MRISC32 CPU) [video]”Submitted Faster C++ builds – Bits'n'Bites as a story · 3 points
HN discussionIt doesn't matter how optimised the length decoding is. Not doing it is still faster. For an 8-wide or 10-wide design, the propagation delays are getting too long to do it in all in single cycle. So you need the extra pipeline stage. The longer pipeline translates to more cycles wasted on branch mispredits. RISC-V code is only about 6-14% denser than Aarch64 [1], I'm really not sure the extra complexity is worth it.…
Comment linking /cisc-vs-risc-code-density/
on “Major Changes at RISC-V Designer SiFive”Submitted Show HN: A luma dependent chroma compression algorithm (image compression) as a story · 1 points
HN discussionJS demos: http://creativejs.com/category/demoscene-2/index.html https://www.bitsnbites.eu/muon-baryon-in-6k-javascript/
Comment linking /muon-baryon-in-6k-javascript/
on “A new line drawing method for the cycle savvy”Submitted Three fundamental flaws of SIMD ISAs as a story · 1 points
HN discussionFork is actually very fast. Too funny a paper coming from Microsoft about fork/exec speed - https://www.bitsnbites.eu/benchmarking-os-primitives/ Linux absolutely destroys the "proper" API. Nearly 40x faster at launching a program with fork+exec than Windows' CreateProcess. Not to mention the fact that vfork has always been available which is even faster. Fork is also pretty scalable, it requires no global locks. It…
Comment linking /benchmarking-os-primitives/
on “The Plan-9 Effect or why you should not fix it if it ain't broken”Submitted Debunking CISC vs. RISC code density as a story · 1 points
HN discussionYou get a nice surprise if you view source too. The demo uses a png to compress the javascript, more details on the author's blog http://www.bitsnbites.eu/?p=20#better_png
Comment linking /?p=20
on “Impressive 4k HTML demoscene”Submitted Denser machine code than C++ code (compiler optimizations) as a story · 1 points
HN discussionSubmitted MRISC32 – Stabilizing the Base Architecture as a story · 1 points
HN discussionSubmitted IEEE 754 suggestion: A “core” subset as a story · 1 points
HN discussion